How AI Agents change how we work with Data Platforms
A chatbot answers questions; a copilot makes suggestions that a human then acts on. An AI agent takes it one crucial step further. It plans multi-step tasks, independently selects tools, executes them within the system, and continues working until the goal is achieved. An open standard makes this possible. The Model Context Protocol (MCP) connects AI assistants with running systems, a kind of universal adapter for AI tools and has been under cross-vendor development since late 2025 under the umbrella of the Linux Foundation. Data and analytics is an ideal field for this, as it features structured metadata, clear interfaces, and a notoriously high level of effort required for analysis, development and operations.
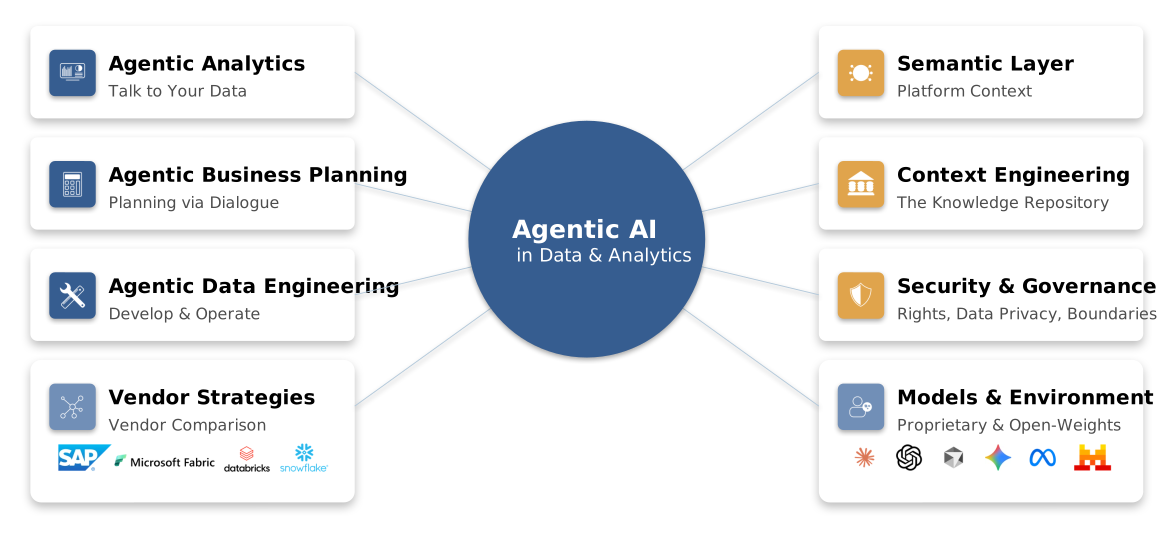
What this means in concrete terms becomes apparent on several levels. Users gain access to their data through natural language; corporate planning can be managed through dialogue; and the development and operation of data platforms are also becoming increasingly agent-driven. The extent to which this applies depends on the strategy the vendor pursues and how open it is to allowing agents into its systems. SAP takes a different approach here than pure data platforms. It also depends on the models and environment you’re working with, as well as on a security and governance framework that holds up in production environments. Above all, however, it is the context an agent is given and how that context is organized, that matters most. After all, in the end, success or failure is rarely determined by the model or the tools alone.
What AI Agents in Data Platforms are capable of today
Agentic AI in Data & Analytics is not a single feature, but rather a set of capabilities. Three of these are particularly prominent in practice today.
Agentic Analytics - Let the Data Speak
Instead of preparing a report, you ask a question in natural language for example, about the five top-selling products each month. The agent selects the appropriate data source from the approved ones, aggregates the data, and responds immediately - even if no report exists for that query yet. All major platforms now support this basic query functionality in production in the SAP Analytics Cloud with “Just Ask” and “Joule,” and on data platforms such as “Genie One” from Databricks or “CoWork” from Snowflake. More exciting is the next level up: generating entire analyses and dashboards via prompts. Here, vendors vary in the scope of their capabilities, ranging from individual report pages as a starting point to complete dashboards, including the import of existing reports from other tools.
Agentic Business Planning - Planning Through Dialogue
Closely related to this and one of the most exciting capabilities for us, is agentic planning. This refers to working with a plan via prompts, changing assumptions, running scenarios and entering plan values through dialogue, without having to click through forms. Taking this concept a step further is the idea of designing the planning application itself using natural language, rather than modeling it in the traditional way.
SAP has the deepest context here, as planning has been part of the analytics stack since the days of BW and remains so in the SAP Analytics Cloud to this day. The roadmap includes several specialized planning agents that work directly with the SAP Analytics Cloud’s planning models, ranging from the Conversational Planning Agent, which changes plan values via prompts, to the Model Creation Agent, which builds planning models itself. Much of this is still in the announcement phase. The data platforms have little to offer in this area. Microsoft is introducing Planning in Fabric, a full-fledged planning application though it is not yet agent-driven while Databricks and Snowflake lack native planning solutions.
This means SAP retains its lead in this capability, even if it currently consists largely of announcements and testing. And this lead is not unchallenged; specialized planning providers are already focusing on the integration of large language models.
Agentic Data Engineering -Developing and Operating Data Platforms
The third capability picks up where IT development has traditionally ended. An agent analyzes existing data models, explains accumulated logic in plain language, creates new objects and data flows, and accelerates migrations, all within the actual system and using the same interfaces as native development tools. This is already standard practice for data platforms; Databricks with Genie Code and Snowflake with CoCo provide agent-based development environments that plan, execute, and debug code. At SAP, Joule has been integrated into SAP Datasphere, but so far it has primarily supported search and catalog maintenance. Agent-based development, in which Joule itself creates models and data flows, does not yet exist.
All of this takes place in the cloud. The many SAP customers who continue to run their data warehouses with BW 7.5 on HANA or BW/4HANA on-premises have so far been left out of agent-driven development. That is precisely why we developed the BW Modeling MCP Server as an open-source project. It connects AI assistants to a running BW system so that they can analyze data models, create objects and build data flows there as well.
And it doesn’t stop at building. Increasingly, the focus is shifting toward agent-driven operations: platforms that optimize themselves, pipelines that detect and fix errors, and loading processes that are monitored and adjusted. At the infrastructure level, this is already a reality for data platforms. A data platform that is completely self-managing does not yet exist, but the direction is clear. The current limit lies where an agent would intervene in production objects without human approval and it is precisely this approval that is still deliberately built into today’s tools.
SAP and Data Platforms: Two Different Worlds
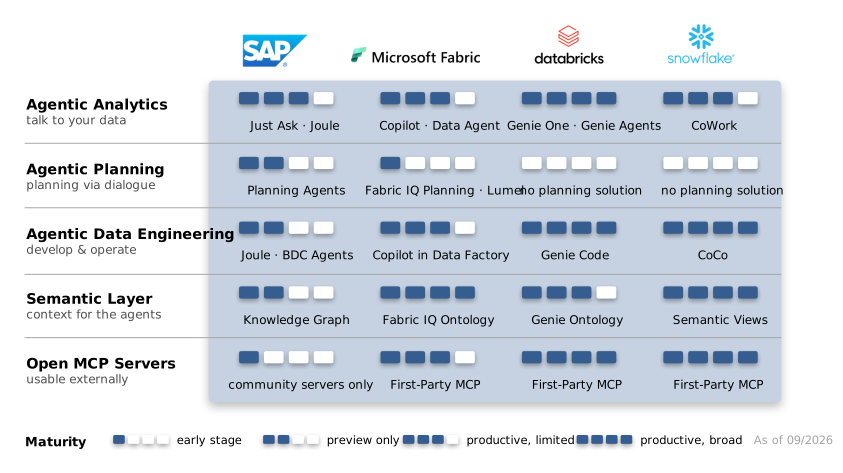
Those who implement Agentic AI in their data landscape will encounter two fundamentally different strategies. The chart summarizes where the four major providers stand today. The real difference, however, lies not in individual levels of maturity, but in their approach.

SAP approaches analytics and planning from an ERP perspective. This provides agents with deep process context right at their fingertips, since the business semantics are already embedded in the suite’s models, and it explains SAP’s lead in planning. At the same time, SAP wants to establish itself as the primary agent-based environment. Joule is intended to become the place where SAP data is processed. This aligns with the fact that SAP does not provide its own MCP server for SAP BW/4HANA, SAP Datasphere, SAP Business Data Cloud, and SAP Analytics Cloud. Anyone who wants to work with these systems from a different agent-based environment must rely on open-source servers from the community that use existing and in some cases undocumented interfaces, with all that this entails for support and governance.

.png?width=300&name=pngwing.com%20(1).png)

The data platforms Microsoft Fabric, Databricks, and Snowflake start from the data. They are more advanced in terms of agent-based development and they provide official MCP servers as part of the product documented, supported and secured through the platform’s permissions. Any MCP-enabled environment can connect and the platform’s semantic layer moves along with it. However, they lack the process context of ERP and planning is not a feature they support.
For an IT manager with a hybrid environment, this offers some peace of mind. He doesn’t have to choose one world over another. Joule is one option - not the only one - and the open connectivity that comes with the data platforms is available for SAP systems from the community, including from us. Because all providers rely on the same open standard, choosing a platform is no longer an irreversible commitment. What carries weight across platforms is the way of working.
Model and environment: how to steer the agents
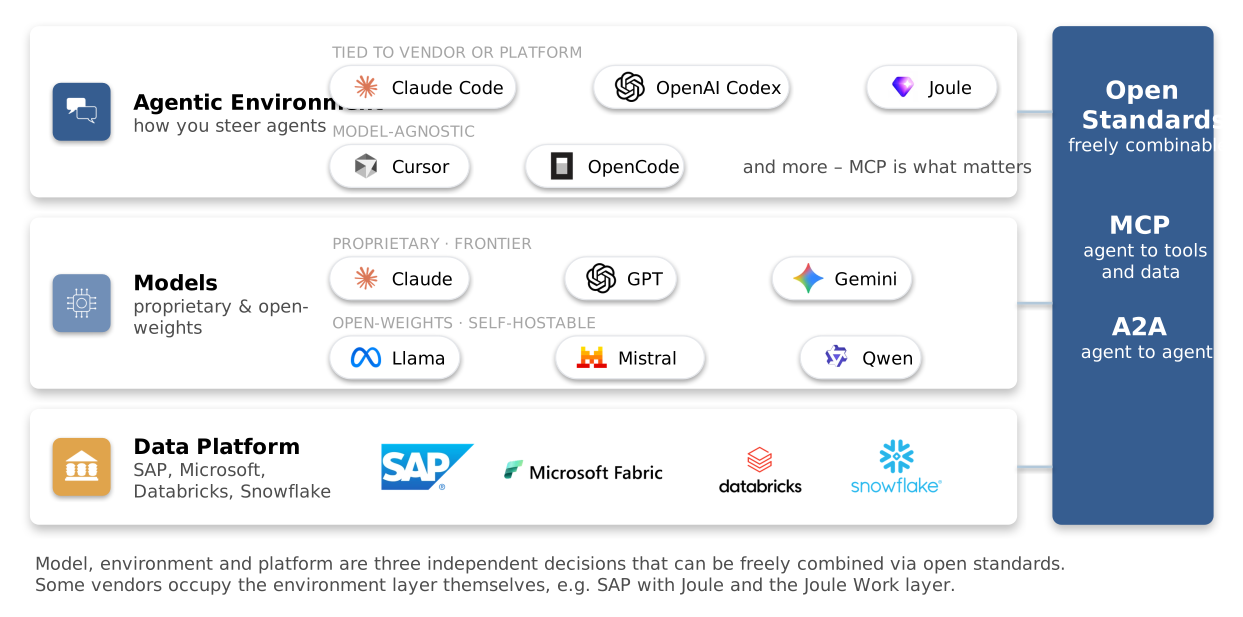
Above the platforms lies a second layer: the models and the agent-based environment used to control the agents. Today, the model, environment and platform are three independent decisions that can be freely combined using open standards. Some environments are tied to a specific model provider, such as Claude Code or OpenAI Codex, while others are tied to a specific platform, such as Joule at SAP, Genie One at Databricks, CoWork at Snowflake, or Microsoft 365 Copilot. Still others are model-agnostic, such as Cursor or OpenCode. The list is constantly growing; what matters is whether an environment supports open standards such as MCP and skills.
Open-weight models have also caught up. Leading open-weight models now perform nearly as well as top-tier proprietary models and can be run independently using published weights. In practice, the choice rarely comes down to a single model; agent-based systems distribute tasks across multiple models and select the most appropriate one based on requirements and costs.
When it comes to the environment, a real question arises, because every vendor offers its own and makes the same argument: their own agent understands the platform’s context without configuration, whereas a third-party agent running via MCP does not. There is a grain of truth to this objection: an agent that uses MCP merely to execute SQL queries against raw tables delivers poor results, regardless of where it runs. However, this does not apply to the open approach as such, because the manufacturers’ MCP servers handle the semantic layer as long as their semantic tools are used. What a proprietary environment, on the other hand, cannot provide is context beyond its own platform, and in heterogeneous environments, it ends at every system boundary. Which environment is used therefore helps determine what an agent is allowed to do and which systems it can access.
Context - what really matters
An agent that requires you to explain again with every task what a table means, how a metric is calculated and how two entities are related will produce inconsistent results. An agent relies on existing structure; it cannot create it on its own. Gartner expects universal semantic layers to be treated as critical infrastructure by 2030, alongside data platforms and cybersecurity, and predicts that by 2027, organizations that prioritize semantics in AI-ready data will increase their agentic AI accuracy by up to 80 percent.*
The platforms themselves provide the first part of this context. Their semantic layer describes entities, relationships, metrics, synonyms and the permissions associated with them - in SAP’s Knowledge Graph and the Business Data Cloud’s data products; in Microsoft’s Fabric IQ and the Power BI semantic model; in Databricks’ Genie Ontology; and in Snowflake’s Semantic Views. All four place this layer at the center of their strategy and all four are working to derive parts of it from existing dashboards, queries, and usage patterns rather than simply modeling it. For an agent, this means they know what revenue means, how the fiscal year is structured and what they’re authorized to view. Through MCP, an external agent receives the same context as an in-house agent.
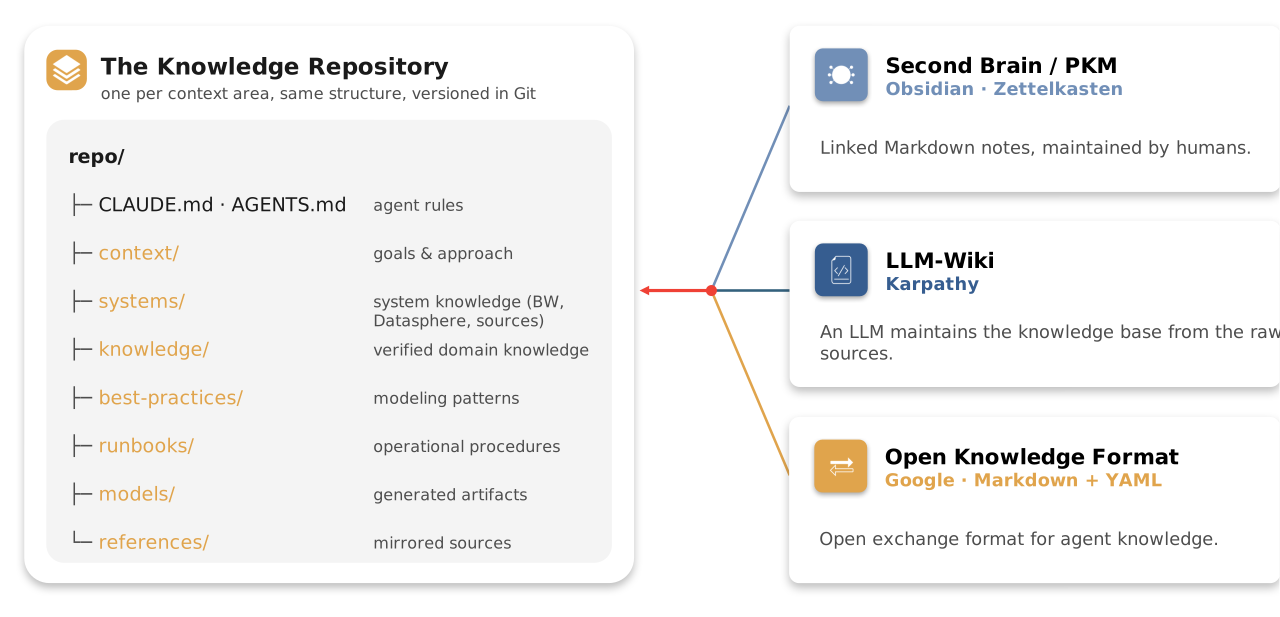
Context engineering is the discipline that organizes precisely this context and makes it permanently available. If prompt engineering is like drafting a single letter, then context engineering is like setting up an entire office. In practice, this results in a version-controlled knowledge repository for each context area that serves both humans and agents alike. Markdown in Git, clearly structured, with rules for the agents, a notation indicating which knowledge is verified and which is not, and with the orchestration of the MCP servers, which make the systems, including their semantic layer, accessible to the agent. No one came up with this pattern on their own. Several strands converge on this, ranging from personal knowledge management to a wiki maintained by a language model, all the way to Google’s Open Knowledge Format, which - since June 2026 - has proposed Markdown with structured metadata as an open specification specifically for this purpose. Setting up such a repository properly, clearly structured, reliably maintained and with the right rules for the agents, is the real art. This is precisely the expertise we bring from our projects, vendor-neutral and across all platforms.
Security, Governance and Limitations
Anyone who includes agents into production data environments needs precise guidelines, and these should be clearly defined. When set up correctly, an agent operates with exactly the same permissions as the logged-in user; what a human is not allowed to do, the AI is also not allowed to do. Read-only access can be granted, write access can be tied to explicit confirmation and production systems can be strictly limited to read-only access. If the connection is managed centrally rather than locally for each user, this adds centralized permission management, identity propagation and end-to-end logging. Governance is not a hindrance here, but rather a prerequisite for delegation in the first place, because you only delegate a task that you can verify, limit, and reverse.
Talk to our expert!
FAQ - Agentic AI in Data & Analytics
Here are some frequently asked questions about Agentic AI in Data & Analytics
Would you like to learn more about Agentic AI?
You'll find some interesting articles on this topic in our blog
The Agentic Turn in Data Engineering: Why Architecture Still Leads
In a previous article we built an AI agent inside Databricks that reads your data, reasons about...
Agentic AI in Practice: MCP Server for SAP BW/4HANA
Back in April, I introduced the bw-modeling-mcp here - an open-source MCP server that allows AI...
Agentic AI meets SAP BW
I’m looking at the UI and just staring at the screen: “Activation in progress… Editor not editable....
/Logo%202023%20final%20dunkelgrau.png?width=221&height=97&name=Logo%202023%20final%20dunkelgrau.png)